Lesson 12 of 14 · about 60 minutes · Updated November 15, 2026
Operational Resilience and Crisis Management
You'll be able to
- Distinguish disaster recovery, business continuity and operational resilience, and say who owns each.
- Describe how a business impact analysis sets maximum tolerable downtime, recovery time and recovery point objectives, and how a board-approved impact tolerance differs from an RTO.
- Summarize what the 2020 interagency Sound Practices paper, the FFIEC booklet, 23 NYCRR 500.16, HIPAA, 42 CFR 482.15, Regulation SCI, DORA and the UK rules expect.
- Apply the lessons of Change Healthcare, CDK Global, CrowdStrike and Colonial Pipeline to crisis teams, communications, workarounds and vendor exit plans.
- Plan an exercise program from tabletop to failover and track after-action findings.
- Explain federal continuity directives and Idaho's continuity requirements for state agencies, and know what public records to request.
Start here: the short version
- Three ideas, three scopes. Disaster recovery brings technology back. Business continuity keeps a business process going, with or without that technology. Operational resilience is the board-level promise that the organization's most important services will keep reaching customers, patients or the public through a disruption, within limits the board has set in advance.12
- Start from services, not systems. A business impact analysis names the critical operations, measures how fast harm grows when they stop, and sets the recovery time, recovery point and maximum tolerable downtime that IT must then meet. An "impact tolerance" or "tolerance for disruption" is the outer limit of harm the organization will accept, approved by the board.34
- Regulators have moved from plans on paper to proof. U.S. bank regulators gathered their expectations in the 2020 Sound Practices paper; New York requires business continuity and disaster recovery plans tested at least annually; the EU's Digital Operational Resilience Act has applied since Jan. 17, 2025 to financial firms operating in the EU, including U.S. groups' EU arms, and in November 2025 put 19 critical technology providers under direct EU oversight.4567
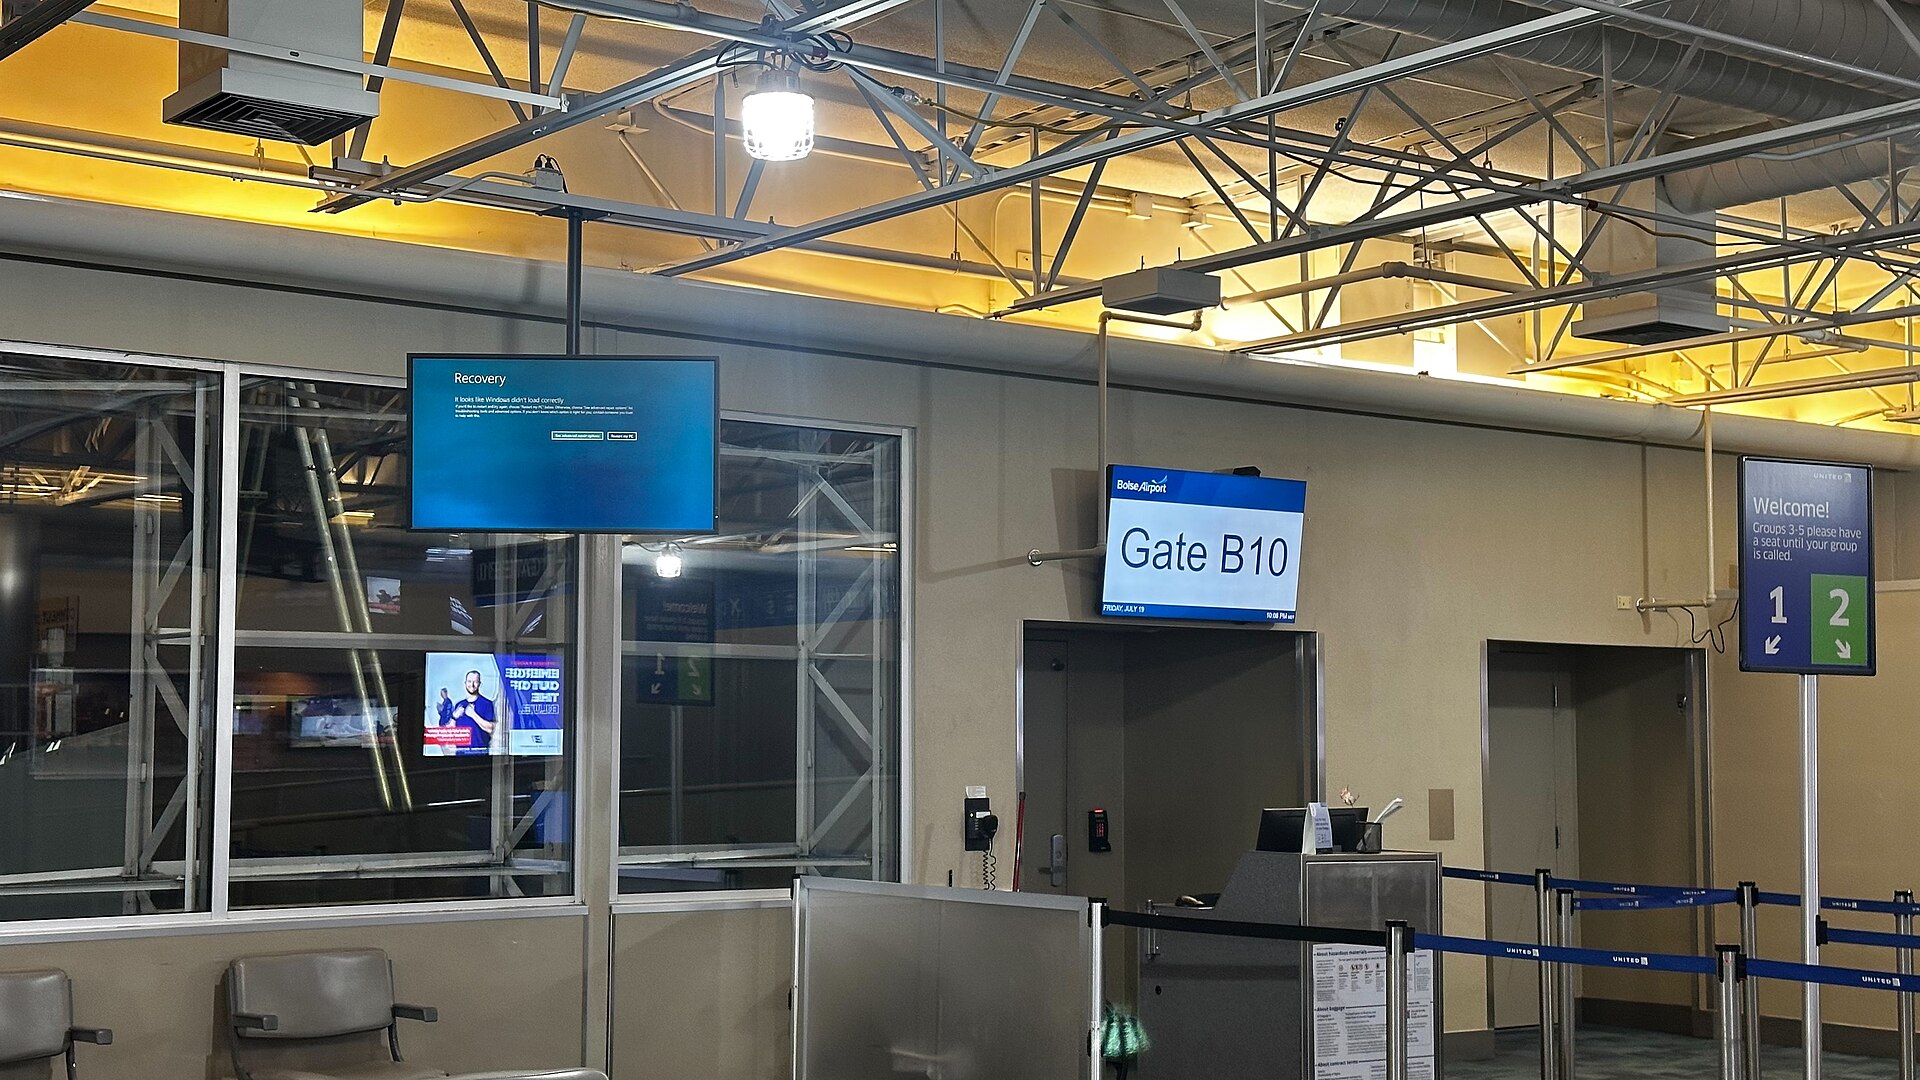
- 2024 was the proof year. Change Healthcare's ransomware attack left pharmacists submitting claims by hand and small practices short of payroll; CDK Global's outage sent car dealers to workarounds; a faulty CrowdStrike update crashed about 8.5 million Windows devices in one night. None of them was a failure of one company alone; all three were failures of dependency.8910
- Crisis management is a separate muscle. A named crisis team, a decision log, pre-approved messages, a single public voice and honest time estimates matter as much as backups. "Days, not weeks" is a promise that can come back to haunt a company.9
- Exercise or it does not exist. Hospitals must exercise their emergency plans at least twice a year; federal agencies must test continuity capabilities on a set schedule and sustain essential functions for at least 30 days; CISA gives away more than 100 tabletop exercise packages.111213
- Idaho has a rule for its own agencies. Executive Order 2022-04 requires every state agency to keep a current continuity of operations plan on file with the Idaho Office of Emergency Management.14
Rules and standards described: Interagency Paper on Sound Practices to Strengthen Operational Resilience (OCC Bulletin 2020-94 and Federal Reserve SR 20-24, Oct. 30 and Nov. 2, 2020; paper revised June 2026 to remove references to reputational risk); FFIEC IT Examination Handbook, Business Continuity Management booklet (Nov. 2019); NIST SP 800-34 Rev. 1 (May 2010, updated Nov. 11, 2010); NIST SP 800-160 Vol. 2 Rev. 1 (Dec. 2021); NIST SP 800-84 (Sept. 2006); NIST Cybersecurity Framework 2.0 (Feb. 26, 2024); ISO 22301:2019 with Amd 1:2024 (described, not reproduced); Regulation (EU) 2022/2554 (DORA), applying from Jan. 17, 2025, and Commission Delegated Regulation (EU) 2025/301; UK FCA operational resilience rules (in force March 31, 2022, with the March 31, 2025 deadline); Basel Committee Principles for Operational Resilience (March 2021); 23 NYCRR 500.16 as amended Nov. 1, 2023; 45 CFR 164.308(a)(7); 42 CFR 482.15; 17 CFR 242.1001 (Regulation SCI); FEMA Federal Continuity Directives of August 2024; Idaho Code 46-1006 and 46-1009 and Idaho Executive Order 2022-04, all read Nov. 15, 2026. Rules, guidance and exercise programs change; check the regulator's current text before relying on any point.
Before you change anything. Plan changes to production systems, test them first, keep a way back, and follow your change management process. For clinical, plant-floor or other safety systems, involve the vendor, your safety lead and qualified engineers (see modules 109 and 111).
At 4:30 on a Thursday morning, the operations center of a regional health system sees its first blue screen. By 5:15 there are hundreds. The electronic health record still runs in the data center, but the nurses' workstations that reach it will not boot, and neither will the badge printers, the pharmacy dispensing cabinets' management consoles or the patient registration desks. Nobody has attacked anything. A security vendor pushed an update overnight. The question the chief operating officer asks at 5:30 is not "what is our recovery time objective for the workstation fleet?" It is "Can we keep admitting patients, giving medications safely and running the emergency department this morning, and for how long?"
That question is what this lesson is about. Module 108 explained the technical half of recovery: backups, restore testing and the recovery numbers (lesson 7) and the incident response machinery (lesson 10). Module 73 covered continuity and insurance at small business scale in Continuity, Recovery and Cyber Insurance. This lesson does not repeat them. It covers how a large or regulated organization decides what must keep working, how much disruption it will tolerate, who runs the crisis, how it talks to the public and regulators while systems are down, how it exercises all of that before it is real, and what regulators in the United States, the European Union and the United Kingdom now expect. It is written for boards and executives, chief risk officers, business continuity and crisis managers, CISOs and CIOs, general counsel's offices and compliance officers, communications directors, public agency heads and emergency managers, and the reporters and legislators who ask afterward why the lights went out.
Inside this module, the insurance that pays for some of the damage is in lesson 9, vendor exits in an acquisition are in lesson 11, recovery metrics for the board are in lesson 3, and the place of resilience in a three-year program roadmap is in lesson 14.
Three ideas: continuity, recovery and resilience
The vocabulary in this field grew in layers, and people still use the words loosely. It helps to pin them down, because each one points to a different owner and a different budget.
Disaster recovery
Disaster recovery is the oldest of the three. It means restoring information systems, data and the facilities that house them after a disruption, usually at an alternate site or cloud region. NIST's contingency planning guide, SP 800-34 Rev. 1 (May 2010, updated Nov. 11, 2010), treats the disaster recovery plan as one of a family of plans and describes it as applying to major, usually physical, disruptions that deny access to the primary facility for an extended period.2 Its owner is the CIO or the head of infrastructure, and its measures are the recovery time objective (RTO) and recovery point objective (RPO) that 108 lesson 7 explains with a diagram.
Business continuity
Business continuity is broader. It asks how a business process, such as paying claims, dispensing medications, settling trades, issuing driver's licenses or running payroll, keeps going during and after a disruption, whether or not its usual technology is available. That includes people (who covers if a team is sick or unreachable), places (where they work if a building is closed), suppliers (what happens if a key vendor fails) and manual workarounds. The FFIEC's Business Continuity Management booklet of November 2019 marked the shift in U.S. bank examination from "planning" to "management": it replaced the 2015 Business Continuity Planning booklet, said that "management should incorporate business continuity into the risk management life cycle," and described resilience as incorporating "proactive measures to mitigate disruptive events."15 Its owner is usually a business continuity office within the operational risk or enterprise risk function, with every business line owning its own plans.
The international standard for a business continuity management system is ISO 22301:2019, "Security and resilience, Business continuity management systems, Requirements," as amended in 2024 by ISO 22301:2019/Amd 1:2024, which added climate action changes to the common management system clauses. Like ISO/IEC 27001, it follows the common ISO management system structure (context, leadership, planning, support, operation, performance evaluation, improvement) and can be certified by an accredited certification body. It is a paid standard; this lesson describes it rather than reproducing it. In plain terms, it asks an organization to define the scope of its program, run a business impact analysis and risk assessment, choose continuity strategies, write and maintain plans, exercise them, and review the whole system through internal audit and management review. Certification is common among data center operators, payment processors and outsourcing firms that sell to banks and governments; for most other organizations the standard is used as a model rather than a certificate.16 Lesson 6 explains how certification audits work.
Operational resilience
Operational resilience is the newest term and the most demanding. The interagency paper the Federal Reserve, the OCC and the FDIC released on Oct. 30, 2020 defines it as "the ability to deliver operations, including critical operations and core business lines, through a disruption from any hazard," and says it is the outcome of effective operational risk management combined with sufficient financial and operational resources.41 Three things set it apart from business continuity:
- It assumes disruption will happen. Business continuity planning traditionally started from a list of threats (fire, flood, pandemic, cyberattack) and planned a response to each. Operational resilience starts from the service and asks how to keep delivering it whatever the cause, which is why regulators talk about "any hazard" and "severe but plausible scenarios."1
- It is measured from the outside in. The test is harm to customers, patients, markets or the public, not whether a particular server came back. The UK Financial Conduct Authority asks firms to set impact tolerances for "the maximum tolerable disruption" to each important business service "without causing harm to consumers, firms or markets."3
- It belongs to the board. In the U.S. paper, the board approves the firm's risk appetite and its "tolerance for disruption"; in DORA, the management body bears "the ultimate responsibility for managing the financial entity's ICT risk."16
NIST's engineering guidance uses a related word, "cyber resiliency," for systems built to "anticipate, withstand, recover from, and adapt to adverse conditions, stresses, attacks, or compromises" on systems that use or are enabled by cyber resources.17 Those four verbs make a useful cycle for leaders, and the diagram below uses them.
Where cyber fits
Cyber incidents are now the disruption most continuity teams plan for first, for a reason that changes the planning: a cyberattack can take out the primary site and the recovery site at the same time. A flood does not follow the data to the backup data center. Ransomware can, if the backup environment shares accounts, networks or management tools with production. A faulty software update reaches every machine running that software, wherever it sits. Traditional disaster recovery assumed an independent second site; cyber resilience assumes the second site may be compromised too, which is why regulators now ask for backups that are protected from alteration, isolated or offline copies, and plans for rebuilding from a known-good state.5118
The NIST Cybersecurity Framework 2.0 (Feb. 26, 2024) puts recovery in its own function, Recover, with two categories: executing the incident recovery plan and communicating about recovery. Under Protect, it asks that mechanisms be in place to meet resilience requirements in normal and adverse situations, and that backups be created, protected, maintained and tested.19 108 lesson 3 maps the framework against other standards.
| Disaster recovery | Business continuity | Operational resilience | |
|---|---|---|---|
| Question it answers | How fast can we restore this system and its data? | How does this process keep running when its normal resources fail? | Can we keep delivering our most important services, within limits we set, whatever happens? |
| Unit of planning | System, application, data center | Business process and its resources | Service delivered to customers, patients, markets or the public |
| Key measures | RTO, RPO, restore test results | Maximum tolerable downtime, workaround duration, staffing | Impact tolerance, time to harm, exercise results against tolerance |
| Usual owner | CIO, infrastructure | Business continuity office and business line leaders | Board and senior management, run through operational risk |
| Main U.S. reference | NIST SP 800-34 Rev. 1 | FFIEC BCM booklet (2019); ISO 22301:2019 | Interagency Sound Practices paper (2020) |
Sources: NIST SP 800-34 Rev. 1; FFIEC Business Continuity Management booklet (Nov. 2019); OCC Bulletin 2020-94 and SR 20-24.2154
The business impact analysis
Everything in this field rests on one document, the business impact analysis (BIA). It answers three questions: what does the organization do that matters most, how quickly does harm grow when each of those things stops, and what does each one depend on? NIST SP 800-34 Rev. 1 treats the BIA as a key step in contingency planning and breaks it into three parts: determine the business processes and how critical their recovery is, identify the resources each one needs, and set recovery priorities for the systems that support them.2 FEMA's August 2024 continuity directive for federal agencies requires the same work under different names: a business process analysis that maps each essential function's tasks, people, systems, information and dependencies, and a business impact analysis that weighs threats, vulnerabilities and consequences.20
How a BIA is done in a large organization
- Set scope and method. The business continuity office writes a short method: which units are in scope, the impact categories and their scales (money, safety, legal and regulatory, customers or patients, reputation with the public), the time points to assess (for example 4 hours, 24 hours, 3 days, 1 week, 30 days), and who must sign the result. The same scales should match the enterprise risk scales in 108 lesson 2, so a continuity risk and a cyber risk can be compared.
- List the services and processes. Start from what customers, patients, members or residents receive, then list the internal processes that produce each one. A hospital's "admit and treat emergency patients" depends on registration, triage, the health record, pharmacy, lab, imaging, bed management and staffing. A bank's "make payments for customers" depends on online banking, the core system, the payment networks, fraud screening and the call center.
- Interview the people who run them. Structured interviews with process owners beat questionnaires; owners tend to under-rate their own processes on paper and over-rate them in conversation, and the analyst's job is to test both with facts: transaction volumes, revenue per day, regulatory deadlines, patient counts, the last outage and what it actually cost.
- Rate impact over time. For each process, score the harm at each time point in each category. The point where harm becomes unacceptable is the maximum tolerable downtime (MTD), which NIST defines as the total time the owner is willing to accept for an outage "and includes all impact considerations."2
- Map dependencies. Record the applications, data, infrastructure, facilities, key people and skills, vendors and their own subcontractors, and other internal processes each process needs. Mark single points of failure. NYDFS requires BCDR plans to identify the "documents, data, facilities, infrastructure, services, personnel and competencies essential to the continued operations" of the business.5
- Derive the technical targets. From the MTD, set the RTO and RPO for each supporting system, leaving time for work recovery (catching up on the backlog) inside the MTD. Compare those targets with what IT can actually deliver today. The gap list is the most useful output of the whole exercise.
- Validate and sign. Business line heads sign their results; the chief risk officer or continuity steering committee resolves conflicts (two units each claiming a 1-hour RTO for the same shared system); senior management approves the overall priorities; the board or its risk committee sees the critical list and the gaps.
- Refresh. At least yearly, and after any acquisition, reorganization, major system change or significant incident. FEMA requires federal agencies to review their mission essential functions every two years.20
The BIA below is illustrative. The organization and every number in it are invented to show how the parts fit, not taken from any real company.
Critical operations, core business lines and important services
Different regulators use different names for the short list at the top of the BIA, and the names carry different meanings:
- Critical operations (U.S. banking): operations whose failure or discontinuance "would pose a threat to the financial stability of the United States." Only the largest banks have them.1
- Core business lines (U.S. banking): business lines whose failure "would result in a material loss of revenue, profit, or franchise value."1
- Important business services (UK): services whose disruption could cause intolerable harm to consumers and markets.3
- Critical or important functions (EU, DORA): functions whose disruption would materially impair a financial entity's performance, soundness or continuity, or its compliance with its license.6
- Mission essential functions and primary mission essential functions (U.S. federal agencies): the functions an agency must continue during a disruption, the most important of which support the national essential functions of government.20
- Material services (NYDFS): the term 23 NYCRR 500.16 uses for what BCDR plans must keep available.5
For an organization that is not regulated in any of these ways, the practical rule is the same: pick the handful of services whose interruption would hurt the people you serve fastest and most, and make those the unit of planning. Most large organizations end up with somewhere between 5 and 30.
Impact tolerances and tolerance for disruption
An impact tolerance is a line drawn on the harm curve before anything goes wrong. The UK regulators made the idea formal: firms had to identify important business services and set impact tolerances by March 31, 2022, and had until March 31, 2025 to show they could keep each service within its tolerance in severe but plausible scenarios, through mapping and testing.3 The U.S. paper uses the phrase "tolerance for disruption" for the same idea, approved by the board as part of its risk appetite and informed by severe but plausible scenarios, and asks firms to test against it.1 The Basel Committee's Principles for Operational Resilience (March 2021) carried the concept to bank supervisors worldwide.21
A good tolerance has four properties. It is stated as harm to the people served, usually as a maximum time (for example, "retail customers can make payments again within 12 hours"), sometimes with a volume or data limit as well. It is set by the business and approved by the board, not by IT. It assumes the disruption has happened, rather than asking how likely it is. And it is tested: the organization runs a scenario and checks whether the service would come back inside the line, with the workarounds actually available. Where it would not, the gap goes on the risk register with an owner, a date and money.
Impact tolerance and RTO are easy to confuse. The RTO is a technical target for one system. The impact tolerance is a limit on harm for a whole service, which may be met by restoring the system, by switching to a manual process, by moving the work to another site or vendor, or by a mix. A bank whose payment system has a 4-hour RTO may still have a 24-hour tolerance for the payment service because it can process urgent payments manually; a hospital whose health record has a 12-hour RTO may have a much shorter tolerance for medication administration and must therefore have paper medication records ready at every unit.
Scenarios: severe but plausible
The U.S. paper asks large banks to develop "severe but plausible scenarios," to compare them against past disruptions, and to map interconnections and concentrations.1 For a cyber program, a useful starting set is: ransomware that encrypts production and the primary backup; destruction of a core system's data with corruption replicated to the recovery site; loss of a critical vendor for 30 days (the Change Healthcare case); a faulty update from a widely used security or management tool (the CrowdStrike case); loss of a cloud region or identity provider; an insider who deletes or alters data; and a regional disaster such as an earthquake, wildfire or long power outage that takes staff away while systems are also impaired. Each scenario is run against the tolerance for each important service; the scenario is "severe" if it would break the tolerance without action, and "plausible" if something like it has happened to someone.

What regulators expect
No single U.S. law requires every large organization to be operationally resilient. Instead, a patchwork of sector rules requires plans, tests and backups, and the banking agencies have gathered their expectations into one paper. The EU and the UK have gone further. This section takes them in turn.
U.S. banks: the 2020 Sound Practices paper
On Oct. 30, 2020 the OCC, the Federal Reserve Board and the FDIC released "Sound Practices to Strengthen Operational Resilience." The paper says plainly that it "does not set forth any new regulations or guidance"; it collects existing rules, guidance and industry standards in one place. It is aimed at domestic banking organizations with at least $250 billion in average total consolidated assets, or at least $100 billion with large amounts of cross-jurisdictional activity, short-term wholesale funding, nonbank assets or off-balance-sheet exposure, but the OCC added that "any bank may find elements of the sound practices useful."4 The Federal Reserve's version (SR 20-24) notes that the paper was revised in June 2026 "to remove references to reputational risk," part of the agencies' broader move away from reputational risk as a supervisory category; the substance on operations did not change.1
The paper is organized in seven areas, each of which maps neatly onto a large organization's program whether or not it is a bank:1
| Area | What the paper expects (in plain terms) | What it looks like outside banking |
|---|---|---|
| Governance | The board approves risk appetite and tolerance for disruption; senior management keeps an accurate picture of the firm's structure and dependencies; audit independently assesses resilience. | A board-approved continuity policy and list of critical services; resilience on the risk committee's calendar; internal audit coverage (lesson 8). |
| Operational risk management | Identify and assess risks to critical operations and core business lines, including third-party exposures; contain disruptions. | Continuity risks on the enterprise risk register with owners and scores. |
| Business continuity management | BIA, plans, testing, training and crisis communications; alternate sites at a sufficient geographic distance; remote work contingencies; testing with third parties where possible. | The program described in this lesson. |
| Third-party risk management | Identify critical dependencies, use formal agreements, monitor performance against tolerance, and consider whether services could be substituted or brought in-house. | Vendor tiers and exit plans (108 lesson 8). |
| Scenario analysis | Severe but plausible scenarios tested against tolerance, compared with past disruptions; map interconnections and concentrations. | Annual scenario set tied to the critical services list. |
| Secure and resilient information systems | Tested protection, detection and recovery for systems supporting critical operations; protect critical data against ransomware, including with secure offline storage. | Immutable or offline backups and restore tests (108 lesson 7). |
| Surveillance and reporting | Monitor operational risk against appetite and tolerance; detect anomalies in time; report to senior management and the board. | Resilience metrics in the board report (lesson 3). |
The paper's Appendix A adds sound practices for cyber risk, organized along the NIST framework functions plus governance and third-party risk.1
The FFIEC Business Continuity Management booklet
For banks and credit unions of every size, the working examination standard is the FFIEC IT Examination Handbook's Business Continuity Management booklet, released Nov. 14, 2019. It covers continuity governance, resilience strategies, plan development, training, exercises and tests, maintenance and improvement, and reporting to the board, and it emphasizes "enterprise-wide, process-oriented approaches" that cover technology, business operations, testing and communication.15 Examiners use it to judge whether a community bank's plan is more than a binder: whether the BIA is current, whether the bank has tested failover with its core processor, and whether the board has seen the results. Banks also face a separate clock: a banking organization must notify its primary federal regulator of a significant "computer-security incident" as soon as possible and no later than 36 hours after determining one has occurred, and its service providers must notify it when an outage could last four hours or more.22
Two more banking rules shape resilience planning. The Bank Service Company Act lets federal banking agencies examine the services that third parties perform for banks "to the same extent as if such services were being performed by the depository institution itself on its own premises," which is how core processors and some technology vendors end up in examiners' sights.23 And the interagency Guidance on Third-Party Relationships, final as of June 6, 2023, asks banks to plan for a relationship's termination, including transition to another provider or bringing the activity in-house, as part of the third-party life cycle.24
Securities markets: Regulation SCI
Exchanges, large alternative trading systems, clearing agencies and certain other market infrastructure fall under the SEC's Regulation Systems Compliance and Integrity (Regulation SCI). It requires business continuity and disaster recovery plans with backup and recovery capabilities "sufficiently resilient and geographically diverse" and "reasonably designed to achieve next business day resumption of trading and two-hour resumption of critical SCI systems following a wide-scale disruption."25 That two-hour figure is one of the few hard recovery numbers written into U.S. regulation, and it is a good benchmark for what "critical" means in practice.
New York: 23 NYCRR 500.16
New York's cybersecurity regulation, as amended effective Nov. 1, 2023, requires every covered entity (banks, insurers and other licensees of the Department of Financial Services) to have written plans "to ensure operational resilience, including but not limited to incident response, business continuity and disaster recovery plans." The BCDR plan must be "reasonably designed to ensure the availability and functionality of the covered entity's information systems and material services" in a cybersecurity-related disruption, and must at minimum identify what is essential, the people responsible, the communications plan, backup procedures and the third parties needed.5 Three operational details matter in a crisis: copies of the plans must be distributed or otherwise "accessible, including during a cybersecurity event," to everyone who needs them; employees responsible for the plans must be trained; and the entity must test, "at a minimum annually," its incident response and BCDR plans "with all staff and management critical to the response" and its "ability to restore its critical data and information systems from backups."5 The business continuity requirements took effect Nov. 1, 2024, one year after the amendment, as 108 lesson 4 explains.
Health care: HIPAA and the CMS emergency preparedness rule
Two federal rules apply to hospitals at once. The HIPAA Security Rule's contingency plan standard (45 CFR 164.308(a)(7)) requires a data backup plan, a disaster recovery plan and an emergency mode operation plan (all "Required"), plus testing and revision procedures and an applications and data criticality analysis (both "Addressable"). The emergency mode operation plan must "enable continuation of critical business processes" that protect electronic health information while the organization operates in emergency mode.26 HHS proposed in January 2025 to tighten these provisions, including restoring critical systems within 72 hours; 109 lesson 3 tracks that proposal's status.
The Medicare conditions of participation add an all-hazards emergency preparedness rule for hospitals (42 CFR 482.15). Hospitals must base an emergency plan on a risk assessment, keep policies and procedures and a communication plan "reviewed and updated at least every 2 years," and "conduct exercises to test the emergency plan at least twice per year," one of them a full-scale or functional exercise and the other a tabletop or similar exercise, analyzing the response to "all drills, tabletop exercises, and emergency events."11 Hospital emergency managers increasingly use one of those two exercises for a cyber scenario, which lets the hospital meet both rules with one event.
The EU Digital Operational Resilience Act
The Digital Operational Resilience Act, Regulation (EU) 2022/2554, known as DORA, has applied since Jan. 17, 2025. It covers banks, investment firms, insurers, payment and e-money institutions, crypto-asset service providers, trading venues, fund managers and other financial entities licensed in the EU. A U.S. financial group is in scope through any EU-licensed subsidiary, and U.S. technology firms feel it as suppliers, because DORA rewrites the contracts EU financial entities sign with them.6 Its main parts, in plain terms:
- Governance. The management body (the board) bears "the ultimate responsibility for managing the financial entity's ICT risk" and approves the ICT business continuity policy and the ICT response and recovery plans (Article 5).6
- ICT risk management, continuity and backup. Firms must keep ICT business continuity and response and recovery plans, test them "at least yearly" for systems supporting all functions, and keep backup policies that specify scope and frequency (Articles 11 and 12).6
- Incident reporting. Major ICT-related incidents must be reported to the competent authority in three stages (Article 19). The implementing rules set the clocks: an initial notification "within four hours from the classification" of the incident as major and no later than 24 hours after the firm became aware of it; an intermediate report within 72 hours of the initial notification; and a final report no later than one month after the latest intermediate report.627
- Testing. A program of resilience testing for all firms, and for the most significant firms, threat-led penetration testing "at least every 3 years" (Articles 24 to 26). Lesson 7 explains threat-led testing.6
- Third-party risk and exit strategies. For ICT services supporting critical or important functions, "financial entities shall put in place exit strategies" that account for a provider's failure or the end of the contract, and test and review them (Article 28(8)). Firms must keep a register of information on all their ICT contracts.6
- Oversight of critical providers. The European Supervisory Authorities (the banking, insurance and securities authorities) designate critical ICT third-party service providers based on systemic impact, the importance of the firms that rely on them, concentration and substitutability (Article 31), and a Lead Overseer can impose periodic penalty payments of "up to 1 % of the average daily worldwide turnover" of a provider that does not comply (Article 35(8)).6 The ESAs published their first list on Nov. 18, 2025.28 A law firm summary counted 19 designated providers, spanning hyperscale cloud, data center, network infrastructure and financial-sector technology firms, and noted that the list will be updated each year.7
For U.S. organizations, DORA matters in three ways even when they have no EU license: as a vendor to EU financial firms (expect contract clauses on audit rights, incident notice, subcontracting and exit support); as the first major regulatory regime to supervise cloud and technology providers directly for resilience; and as a model that U.S. regulators and boards can borrow from.
The United Kingdom and the Basel Committee
The UK's Financial Conduct Authority, Prudential Regulation Authority and Bank of England adopted parallel operational resilience rules in force from March 31, 2022. Firms had to identify important business services, set impact tolerances, map the people, processes, technology, facilities and information behind each service, test against severe but plausible scenarios, prepare internal and external communications for disruption, and write a self-assessment. The transition ended March 31, 2025, by which date firms had to be able to remain within tolerance.3 The Basel Committee on Banking Supervision's Principles for Operational Resilience, published March 31, 2021, set seven principles for banks worldwide covering governance, operational risk management, business continuity planning and testing, mapping of interconnections, third-party dependency management, incident management and resilient technology including cyber security.21 U.S. firms with UK or international banking operations work under these regimes in those jurisdictions, and many apply the impact tolerance method group-wide because it is the clearest way to make the board's appetite measurable.
| Regime | Who | Core resilience demand | Test frequency stated |
|---|---|---|---|
| Interagency Sound Practices (Oct. 30, 2020) | Largest U.S. banks (useful to all) | Board-set tolerance for disruption; seven areas | Not fixed; regular testing against scenarios |
| FFIEC BCM booklet (Nov. 2019) | All U.S. banks and credit unions | Enterprise-wide continuity management | Examiner judgment; at least annual is the norm |
| Regulation SCI | Exchanges and key market systems | Two-hour resumption of critical SCI systems | Annual industry or sector-wide testing for designated members |
| 23 NYCRR 500.16 | NYDFS licensees | Written IR and BCDR plans; protected backups | At least annually, plus annual restore tests |
| 45 CFR 164.308(a)(7) | HIPAA covered entities and business associates | Backup, disaster recovery and emergency mode plans | Periodic (addressable) |
| 42 CFR 482.15 | Medicare and Medicaid hospitals | All-hazards emergency plan, communication plan | Exercises at least twice per year |
| DORA (from Jan. 17, 2025) | EU financial entities | ICT continuity, incident reporting, exit strategies | Plans at least yearly; TLPT at least every 3 years |
| UK FCA and PRA (March 31, 2025 deadline) | UK banks, insurers, larger firms | Impact tolerances for important business services | Regular scenario testing |
| FEMA continuity directives (Aug. 2024) | Federal executive branch agencies | Essential functions within 12 hours, sustained 30 days | Annual or biennial exercises by function type |
Sources: the regulations and guidance cited in this section.4152552611631220 The Regulation SCI testing row reflects the rule's separate business continuity testing requirement for designated members, described here in general terms.
Three disruptions of 2024 and what they taught
108 lesson 8 tells the vendor side of these three events. Here the question is different: what did they show about running an organization while its own or a supplier's systems were down?
Change Healthcare: when the whole sector shares one pipe
Change Healthcare, a unit of UnitedHealth Group's Optum, moves claims, eligibility checks and payments between providers, pharmacies and insurers. Criminals entered on Feb. 12, 2024 through a remote access portal that "did not have multi-factor authentication," and deployed ransomware on Feb. 21. UnitedHealth's chief executive, Andrew Witty, told the Senate Finance Committee on May 1, 2024 that the disruption ran "from pharmacists having to manually submit claims to the rural family medicine practice struggling to make payroll."8 His testimony describes the company's recovery choices in terms any crisis team can learn from:
- Rebuild rather than restore. The response team "replaced thousands of laptops, rotated credentials, rebuilt Change Healthcare's data center network and core services, and added new server capacity," delivering "a new technology environment in just weeks."8 When an environment cannot be trusted, recovery means a clean rebuild, and the plan must say in advance which services get rebuilt first.
- Prioritize by harm. The company said it prioritized restoring the systems "most critical to access to care: pharmacy, provider payments and claims."8 That is an impact tolerance decision made under pressure; organizations that make it in advance make it faster.
- Bridge the money gap. As of April 26, 2024, UnitedHealth had advanced more than $6.5 billion in accelerated payments and no-interest, no-fee loans to providers, and Witty acknowledged that some early estimates of providers' needs "did not address their full need given our lack of visibility into their claims flow."8 A vendor's outage became its customers' cash flow crisis.
The data side was just as large: HHS's Office for Civil Rights reports that Change told it on July 31, 2025 that about 192.7 million people were affected.29 For customers, the resilience lesson was blunt. A provider or pharmacy with a contract and a tested connection to a second clearinghouse had somewhere to send claims; one without had to arrange that during the crisis, while claims piled up. The concentration was not visible on most risk registers because each organization saw only its own contract. OCR's report for calendar year 2024 shows how much health care risk now sits with vendors: breaches at business associates were 16 percent of large breach reports but affected about 85 percent of the people.30
CDK Global: expectations and workarounds
CDK Global supplies a hosted dealer management system to more than 15,000 car dealers in North America. It discovered a cyberattack on June 19, 2024 and shut systems down. Dealers stayed open using what one report called "workarounds to minimize disruption." Five public dealer groups filed SEC disclosures within days; Group 1 Automotive's filing relayed CDK's expectation that the system would be restored "within several days, not weeks," and Lithia Motors said the incident "has had, and is likely to continue to have, a negative impact" on operations.9
Two lessons stand out. First, a vendor's early time estimate travels: it ends up in customers' securities filings and press statements, and if it proves optimistic, every customer's credibility suffers with it. Crisis communicators should give ranges and conditions ("we expect to restore core functions in stages; we will update by Friday") rather than single numbers. Second, dealers kept selling and servicing cars only because workarounds existed. A manual workaround that nobody has practiced is a hope, not a plan.
CrowdStrike: the accident everyone shared
On the night of July 18 to 19, 2024, a faulty content update for CrowdStrike's Falcon sensor crashed Windows machines. Microsoft estimated that it "affected 8.5 million Windows devices, or less than one percent of all Windows machines," and said the broad impact reflected "the use of CrowdStrike by enterprises that run many critical services." Microsoft deployed hundreds of engineers to help customers and posted manual remediation instructions.10 CrowdStrike's root cause analysis of Aug. 6, 2024 said that, as of July 29, about 99 percent of Windows sensors were back online, and listed its fixes: more testing of content before release, staged deployment in which updates are "successively promoted to wider deployment rings or rolled back if problems are detected," and new controls letting customers "choose where and when" rapid response content is deployed.31
For resilience planners, CrowdStrike made three points. The disaster recovery site did not help, because the same agent ran there too. Recovery was limited by hands, not by backups: Microsoft's response included posting manual remediation instructions, which meant many organizations needed people to reach affected machines. And an organization that had already ranked its machines by the services they support could fix the most important ones first. Every large organization should now ask of each high-privilege tool (endpoint security, device management, remote access, identity) whether it controls when updates land on its most critical machines, and what it would do if that tool took them all down at once.
Colonial Pipeline: when business systems stop operations
The 2021 Colonial Pipeline ransomware attack remains the clearest public example of a business IT incident stopping physical operations. Colonial's chief executive, Joseph Blount, told the Senate Homeland Security Committee on June 8, 2021 that the company shut down the pipeline as a precaution: "if there was one percent chance that that OT system was compromised, it was worth shutting the pipeline system down." Asked whether Colonial could run the pipeline manually, he said it "did operate small portions of the pipeline manually," but that the operations team judged "it would be quicker to get back up on our feet by correcting the corruption of the critical IT systems." He also described keeping the line under pressure, with "people manually in the field looking at gauges, the old-school way," so it could restart quickly.32
The lesson for any organization with physical operations is to know, before the incident, which operational processes depend on business systems (billing, scheduling, logistics, customer records), whether they can run without them and for how long, and who has the authority to stop operations. 111 lesson 1 explains the IT and OT split, and 111 lesson 5 covers safe shutdown and restart.
Concentration risk and exit plans
Concentration risk is the risk that many critical services depend on one provider, one technology, one location or one person, so that a single failure takes them all down. It shows up at three levels:
- Inside the organization: one identity provider for every login, one cloud region for every critical system, one backup platform whose administrator accounts could be stolen, one data center building, one engineer who understands the mainframe batch schedule.
- Across a sector: one clearinghouse for most of health care's claims, one dealer management vendor for many dealers, a few core processors for most community banks.
- Across the economy: a handful of hyperscale cloud providers and security agents that sit on most enterprise machines. This is the level DORA's oversight of critical providers addresses.67
Concentration is not always bad. A large cloud provider may be far more reliable than an organization's own data center, and one well-run identity platform is often safer than five poorly run ones. The governance task is to know where the concentrations are, decide which ones the board accepts, and have a plan for each accepted concentration failing.
What an exit plan contains
DORA requires exit strategies for ICT services that support critical or important functions, and the U.S. banking agencies' 2023 third-party guidance asks for termination and transition planning.624 Two kinds of exit need planning: a stressed exit, when the provider fails suddenly (bankruptcy, a cyberattack, a sanctions event), and a planned exit, when the contract ends or the relationship sours. A workable plan for each critical provider names:
- The services and data involved, and which important services depend on them.
- The trigger events and who decides to invoke the plan.
- The alternative: another provider already under contract, a provider that could be contracted quickly, an in-house capability, or a manual process, with the realistic time each would take.
- Data portability: in what format the data can be extracted, how long it takes, whether the organization holds its own current copy, and the contract right to get it back.
- Contract terms that support exit: transition assistance, continued service during a notice period, escrow of code or configuration where useful, and the right to audit.
- Cost and funding, approved before the event.
- Test results: at minimum a tabletop walk-through, and for the most critical services a technical test of data extraction or failover.
The hardest honest answer in many exit plans is "no realistic alternative within our tolerance." That answer belongs in front of the board, not buried in a vendor file, because only the board can accept that risk, pay to reduce it, or ask the business to change.

Crisis management
Incident response, as 108 lesson 10 describes it, is a technical discipline: contain the attacker, find the scope, remove the foothold, restore. Crisis management sits above it. It deals with the decisions that only executives can make (stop operations, divert patients, pay or refuse a ransom, tell investors, close branches), with the people affected, and with the organization's public voice. NIST lists a crisis communications plan as one of the plans that work alongside the information system contingency plan, and NIST's incident response guidance, SP 800-61 Rev. 3 (April 3, 2025), ties incident response to the whole organization's risk management rather than treating it as an IT function.233
The crisis management team
Large organizations use a tiered structure. Names vary, but the pattern is consistent:
| Tier | Who | What it decides |
|---|---|---|
| Strategic (often "gold" or executive crisis team) | CEO or a designated executive as crisis lead; CFO; COO; general counsel's office; CISO and CIO; chief risk officer; communications; human resources; for hospitals the chief medical and nursing officers; for agencies the agency head and public information officer | Priorities and tolerances in this event; stop or continue operations; external statements; regulatory and investor disclosures; ransom questions; spending authority; when to brief the board |
| Tactical ("silver" or incident command) | Business continuity manager, incident response lead, IT operations, facilities, business line continuity leads | How to deliver the strategic priorities: which workarounds to activate, staffing, sequence of recovery |
| Operational ("bronze" or response teams) | Technical responders, business units running manual processes, call centers, field staff | Doing the work and reporting status |
| Board | Chair, lead director, chair of the risk or audit committee | Oversight; questions; major decisions the charter reserves to the board |
Hospitals and public agencies usually map these tiers onto the Incident Command System they already use for physical emergencies, with a cyber or IT section added; that saves inventing a second structure. Whatever the model, five things should be settled before any incident: who is the crisis lead and two named alternates; how the team is convened when email, phones or the collaboration platform may be compromised (an out-of-band channel with pre-loaded contacts); who keeps the decision log, recording each decision, the time, the facts known and the reasons, which later supports regulatory filings, insurance claims and litigation holds; what spending authority the crisis lead has; and when the board is told. NYDFS's requirement that plans be accessible during a cybersecurity event is a reminder that a plan stored only on the encrypted file server is not available when needed.5
The first twenty-four hours
The first day decides most of what follows. A typical sequence for a large organization hit by a disruptive cyber event:
- Hour 0 to 1: declare and convene. The incident lead declares a crisis level under pre-set criteria (for example, an important service is down or at risk of breaching tolerance) and the crisis team meets on the out-of-band channel.
- Hour 1 to 2: protect life and safety; decide on containment that stops operations. Start downtime procedures, divert patients or stop a plant if the facts require it. Colonial's choice to stop the pipeline was this decision.32
- Hour 1 to 4: start the clocks. Identify every notification clock that may be running: the insurer's hotline, the 36-hour banking notice, the four-hour DORA initial notice for an EU entity once an incident is classified as major, NYDFS's 72-hour notice34, and the materiality analysis that drives an SEC Form 8-K within four business days of a materiality decision.222735 108 lesson 11 has the full list.
- Hour 2 to 6: first internal message, first holding statement. Staff hear first and from the organization, with clear instructions (what to use, what not to use, where to get updates). A short public holding statement says what is known, what customers should do, and when the next update will come.
- Hour 4 to 12: activate workarounds and prioritize recovery. Using the BIA, decide which services come back first and which manual processes start now.
- Hour 12 to 24: first board briefing, regulator contact, customer channels. Set a fixed update rhythm (for example, every 4 hours internally, every 24 hours externally) and keep to it.
This sequence is a general pattern, not a legal checklist; sector rules and the organization's own plan set the actual obligations.
Crisis communications
Communications failures cause as much lasting harm as technical failures, and they are more avoidable. The 2024 events, and years of SEC enforcement over misleading incident statements, support a short list of principles:
- One voice, many channels. A single spokesperson and a single source of truth (a status page hosted outside the affected environment), with consistent messages to staff, customers, regulators, investors and the press.
- Say what you know, what you do not know, and when you will say more. Do not speculate about the attacker, the data or the timeline.
- Give ranges, not promises. The CDK "several days, not weeks" estimate, relayed in a customer's SEC filing, shows how a single number becomes a public commitment.9
- Say what people should do. Pharmacies, dealers and patients needed instructions more than reassurance.
- Do not minimize. The SEC has charged companies for describing incidents as hypothetical or limited when they knew otherwise; 108 lesson 4 covers those cases.
- Apologize when it is owed. Witty told the committee in his written testimony, "I am deeply sorry."8 A plain apology does not admit legal liability by itself, and its absence is noticed.
- Coordinate with partners. Blount told the Senate that communicating with the federal government "through one conduit" was "extremely valuable" for a management team "already stretched."32
Hospitals have a specific duty here: the CMS rule requires an emergency communication plan with contact information for staff, physicians, other hospitals and emergency management officials, reviewed at least every two years.11 The sample Crisis Communications Plan outline later in this lesson puts these pieces in order.
Manual workarounds and downtime procedures
A workaround is the way a process keeps running when its system does not. In hospitals these are called downtime procedures: paper order sets, medication administration records and lab requisitions; printed census and medication lists produced on a schedule so they exist when the system fails; runners carrying results; read-only "downtime viewer" computers holding recent patient summaries; and rules for re-entering paper records once systems return. HIPAA's emergency mode operation plan requirement and the CMS emergency preparedness rule together make downtime planning a legal duty for hospitals, not only good practice.2611 109 lesson 7 covers clinical technology.
Outside health care, the same idea applies: manual payment authorization with call-back verification at a bank, paper repair orders at a dealer, manual dispatch cards at a 911 center, paper ballots and pollbooks as backup at elections, field crews reading gauges as Colonial did.32 Four rules make workarounds real:
- Write them down for each important service, with forms printed and stored where staff work.
- Pre-stage the information they need (contact lists, recent records, account lists), refreshed on a schedule and kept off the main network.
- Drill them with the people who will do them, during real shifts, not only in a conference room.
- Plan the catch-up: how paper work gets entered later, by whom, with what checks, and how long it takes. The catch-up time is part of the maximum tolerable downtime.
Workarounds also have security risks of their own. Criminals know that an organization in downtime is accepting changes by phone and email; payment fraud and fake "IT support" calls spike during outages. Call-back verification of any change to payment instructions, as 110 lesson 6 explains, matters more in a crisis, not less.
Recovery metrics
Boards and regulators increasingly ask for resilience numbers, not adjectives. Useful measures, reported in the board pack described in lesson 3:
| Measure | What it shows | Watch for |
|---|---|---|
| Share of important services with a current BIA, tolerance and tested plan | Coverage of the program | Plans counted as "tested" after a tabletop only |
| Services whose demonstrated recovery time in the last test fits inside tolerance | Whether the board's limits are achievable | Tests that excluded the hard parts (identity, data validation, catch-up) |
| Gap between required RTO and demonstrated RTO for critical systems | Investment needed | RTOs set by IT without business input |
| Restore tests completed and success rate; age of oldest untested backup set | Whether backups are real (108 lesson 7) | Restores of a single file reported as a system restore |
| Critical vendors with a tested exit or substitution plan | Concentration risk being managed | Exit plans that say "to be determined" |
| Exercise findings open past due date | Whether lessons are learned | Same finding in three years of after-action reports |
| For real events: time to declare, time to first statement, time to restore each important service, time to clear backlog | Actual performance | Clock starting at "declared" rather than "first detected" |
Exercises from tabletop to full failover
NIST's guide to test, training and exercise programs, SP 800-84 (September 2006), still gives the basic vocabulary: training teaches people their roles; exercises (tabletop and functional) simulate an emergency to check whether people can carry out the plan; tests check whether a system or component works as intended.36 A mature program runs a ladder of exercises, each harder and more realistic than the last:
- Plan walk-through. Owners read the plan together and fix errors: missing contacts, retired systems, steps that no longer apply.
- Tabletop exercise. A facilitator leads a scenario in stages ("injects"); participants discuss what they would do. Cheap and good at exposing decision gaps, unclear authority and missing information. The executive tabletop that reaches the materiality decision and the draft 8-K belongs here.
- Functional exercise. Teams actually perform functions in a simulated setting: the crisis team convenes on the out-of-band channel, a business unit runs its manual process for a shift, the call center switches scripts.
- Technical recovery test. Restore a system from backup into an isolated environment and prove it works with real data, timed against the RTO.
- Failover test. Run production from the alternate site or region for a period, then fail back. Expensive and risky, so it is planned like any production change.
- Full-scale or sector exercise. Many organizations and agencies play together, often with regulators and government partners.
Any live failover, restore into production or shutdown drill is itself a change to production systems; plan it, test it in a lower environment first, and have a way back.
Free materials make the lower rungs easy. CISA offers more than 100 CISA Tabletop Exercise Packages, each with template objectives, scenarios and discussion questions, role guidance for planners and facilitators, invitation and slide templates, a feedback form and an after-action report template, with cyber scenarios including ransomware, insider threats, phishing and industrial control system compromise, and sector versions for local governments, elections, water, ports and health care.13 CISA also runs a national-level exercise series called Cyber Storm, which brings federal agencies, states, international partners and private companies together in a simulated large-scale cyber crisis; the dates and participants of the most recent edition could not be confirmed for this lesson. Sector groups, such as the information sharing and analysis centers, and some regulators run their own exercises for members.
After-action reports
An exercise is only as good as what changes afterward. Each one should produce an after-action report with what went well, what did not, the root cause of each gap, a corrective action with an owner and date, and a tracking number. The CMS rule requires hospitals to "analyze the hospital's response to and maintain documentation of all drills, tabletop exercises, and emergency events, and revise the hospital's emergency plan, as needed."11 Internal audit should sample open findings yearly; the board should see the count of overdue items. The same discipline applies to real incidents, which are the most valuable exercises an organization will ever get.
The public sector: continuity of operations
Government uses its own vocabulary. Continuity of operations (COOP) is an agency's ability to keep performing its essential functions during a disruption; continuity of government is the wider question of keeping lawful leadership and authority in place. For the federal executive branch, FEMA's Office of National Continuity Programs issued two new Federal Continuity Directives in August 2024 that rescinded and replaced the older directives from 2017:
- Federal Executive Branch Continuity Program Management Requirements replaced Federal Continuity Directive 1 (January 2017). It organizes continuity into four phases (readiness and preparedness, activation, continuity operations, and establishing a new normal) and four "interconnected planning factors": staff and organization, equipment and systems, information and data, and sites. Plans must include a way to sustain operations "for a minimum of 30 days." It sets a testing schedule that includes monthly alert roster tests, quarterly communications tests and annual recovery and information system tests, and requires exercises annually for each primary mission essential function or every two years for each mission essential function, plus an annual command and control exercise. It names a "cyber incident threat or occurrence" as an activation trigger and covers devolution (transferring authority to other staff or sites) and reconstitution.12
- Federal Executive Branch Essential Functions Risk Identification and Management replaced Federal Continuity Directive 2 (June 2017). Agencies must identify their essential functions, run a business process analysis and a business impact analysis, choose among continuity options (distribution, devolution, relocation and hardening), review their functions "every two years," and be able to perform essential functions "as soon as possible, but not later than 12 hours after continuity plan activation," sustained for at least 30 days.20
The 12-hour and 30-day figures are useful benchmarks for state and local governments too, which are not bound by the federal directives but often follow FEMA's templates. Counties, cities and school districts face the hardest version of the problem: they run 911 dispatch, elections, utilities, jails and benefits with small IT staffs, and their continuity plans were often written for floods and fires. A ransomware attack that takes out the county's network can also take out the computer-aided dispatch system, property records and payroll at once.
Idaho
Idaho's framework comes from the State Disaster Preparedness Act. Under Idaho Code 46-1006, the adjutant general represents the governor "in all matters of disaster services," coordinating state agencies, and the Idaho Office of Emergency Management (IOEM) must "prepare, maintain and update a state disaster plan."37 Under Idaho Code 46-1009, every county must be served by IOEM and by a county or intergovernmental disaster agency, or have a liaison officer appointed by the county commission.38
For state agencies, IOEM's continuity page states the rule plainly: "Executive Order 2022-04 designates the IOEM as the coordinator of State and federal emergency response, recovery and mitigation operations during emergencies and disasters. It also requires each State Agency to maintain a current COOP Plan to be kept on file at the IOEM." IOEM describes COOP as an agency effort "to ensure they can continue to perform mission essential functions during a disruption of normal operations," including delegation of authority, alternate work locations, protection of assets and recovery.14
IOEM also administers Idaho's share of the federal State and Local Cybersecurity Grant Program. Its program page says Idaho's planning committee chose to deliver services rather than small cash grants, with estimated statewide costs of $900,000 for risk assessment and gap management, $450,000 for cybersecurity governance and planning ("assisting with the establishment of governance structures, cybersecurity policies, and response plans") and $330,440 for training, delivered in part through regional Cybersecurity Area Field Officers who work with counties, cities, school districts and special districts.39 Lesson 2 discusses that grant program's funding.
Idaho's health care sector has its own recent case: Kootenai Health in Coeur d'Alene reported a 2024 ransomware attack affecting about 464,088 people, according to a filing with the Maine attorney general reported by SecurityWeek.40 Idaho public agencies that suffer a breach must notify the Idaho Attorney General within 24 hours under Idaho Code 28-51-105.41

Sample policies
Sample only. Adapt it to your organization's risks, systems and laws, have qualified people review it, and do not treat it as a substitute for a risk assessment.
Follows: Interagency Paper on Sound Practices to Strengthen Operational Resilience (2020, revised June 2026); FFIEC Business Continuity Management booklet (Nov. 2019); NIST SP 800-34 Rev. 1 and SP 800-84; NIST CSF 2.0 (RC.RP, RC.CO); 23 NYCRR 500.16; 45 CFR 164.308(a)(7); 42 CFR 482.15; Regulation (EU) 2022/2554 Articles 5, 11, 12 and 28; FEMA Federal Continuity Directives (Aug. 2024); ISO 22301:2019 as described. Written for this module on Nov. 15, 2026.
Business Continuity and Crisis Management Policy
1. Purpose
[Organization name] provides services on which [customers / patients / members / residents] depend. This policy sets how the organization identifies its important services, sets limits on the disruption it will tolerate, plans and tests to stay within those limits, and manages crises when they occur.
2. Scope
All business units, subsidiaries, locations and staff; all information systems and facilities; and all third parties that support an important service.
3. Roles
- [Board / Risk Committee]: approves this policy, the list of important services and their impact tolerances at least every [12] months; receives the annual resilience report and reports of any breach of tolerance within [24] hours.
- [Chief Executive Officer]: accountable for the program; designates the crisis lead and two alternates.
- [Chief Risk Officer]: owns this policy; chairs the Resilience Steering Committee; reports to the board.
- Business Continuity Manager: runs the BIA, maintains plans and the exercise calendar, tracks findings.
- [CIO] and [CISO]: deliver disaster recovery capabilities that meet approved RTOs and RPOs; protect backups from alteration; run technical recovery tests; lead technical incident response.
- Business line heads: own the continuity plans and workarounds for their processes and staff them for exercises.
- [Vendor Management Office]: keeps exit and substitution plans for every critical third party.
- [Communications Director]: owns the Crisis Communications Plan.
- Internal Audit: independently assesses the program at least every [two] years.
4. Important services and impact tolerances
The organization maintains a list of important services. For each, it sets an impact tolerance stated as the maximum duration [and volume or data loss] of disruption beyond which harm to [customers / patients / the public / markets] or to the organization's safety and soundness would be intolerable. Tolerances assume the disruption occurs and are not reduced by its likelihood.
5. Business impact analysis and mapping
A BIA covering every important service is completed at least every [12] months and after any major change. It records processes, maximum tolerable downtime, RTO and RPO for supporting systems, people and skills, facilities, data, internal dependencies and third parties (including their critical subcontractors), and single points of failure.
6. Continuity and recovery strategies
Each important service has documented strategies to stay within tolerance, which may include alternate sites at sufficient geographic distance, alternate cloud regions, protected and isolated backups, rebuild procedures from a known-good state, alternate suppliers, and manual workarounds. Manual workarounds are documented, pre-staged and drilled. Planned production changes to implement strategies are tested before deployment and have a rollback plan.
7. Third parties and concentration
Critical third parties are identified and contractually required to maintain and test continuity plans, notify the organization of disruptions within [4] hours, support exit and data return, and participate in exercises where possible. The organization keeps a tested exit or substitution plan for each, and reports accepted concentrations to the [Risk Committee].
8. Crisis management
The Crisis Management Team is convened under the criteria in the Crisis Management Plan through an out-of-band channel. The crisis lead may [authorize spending up to $ ___, order operational shutdowns, activate workarounds]. A decision log is kept for every crisis. Current copies of all plans are kept accessible during a cyber event, including off-network copies.
9. Testing and exercises
At minimum: annual plan review; annual tabletop exercise for each important service; annual executive crisis exercise including disclosure decisions; restore tests of critical systems at least [annually]; failover tests for [named systems] at least [every two years]; participation in [sector / regulator] exercises. After-action reports are issued within [30] days with tracked corrective actions.
10. Reporting and review
The board receives an annual resilience report covering coverage, test results against tolerance, open findings, concentrations and incidents. This policy is reviewed at least every [12] months. Exceptions are approved by the [Chief Risk Officer] and reported to the [Risk Committee].
Sample only. Adapt it to your organization's risks, systems and laws, have qualified people review it, and do not treat it as a substitute for a risk assessment.
Follows: 23 NYCRR 500.16(a)(2) (communications in BCDR plans); 42 CFR 482.15(c) (hospital emergency communication plan); NIST CSF 2.0 RC.CO (incident recovery communication); NIST SP 800-34 Rev. 1 (crisis communications plan); SEC Form 8-K Item 1.05 (Release 33-11216); lessons from the Change Healthcare, CDK Global and Colonial Pipeline public records. Written for this module on Nov. 15, 2026.
Crisis Communications Plan: outline
- Purpose and activation. When the plan is activated (any crisis level [2] or higher), and who activates it.
- Roles. Spokesperson and alternate; communications lead; approvers for external statements ([crisis lead, general counsel's office, CISO]); investor relations; regulator liaison; employee communications; customer service lead; social media monitor.
- Audiences and channels. Staff; [customers / patients / residents]; regulators (list each with its notice clock); investors; insurers; key vendors and partners; media; elected officials; law enforcement. For each: the channel, the owner and the update rhythm.
- Out-of-band tools. Status page hosted outside the organization's environment; mass notification system; pre-loaded phone trees; printed contact lists kept at [locations].
- Pre-approved templates. Staff notice ("what to use, what not to use"); holding statement; customer instructions; vendor notice; regulator initial notice; board briefing; call center script; social media post. Each with [brackets] for facts.
- Rules. Say what is known, what is not, and when the next update comes. Give ranges, not promises. No speculation about attackers or data before facts are confirmed. Every external statement is checked against what has been told to regulators and investors. Corrections are issued promptly.
- Disclosure coordination. How the communications team works with the disclosure committee on materiality and Form 8-K timing, and with privacy staff on breach notices.
- Fraud warning. Standing message that the organization will not ask for passwords or payment changes by phone or email during the outage, and how to verify.
- Close and review. Final statement; thank-you to staff and partners; after-action review of communications within [30] days.
- Appendices. Contact lists (refreshed [monthly]); templates; regulator notice table; media list; glossary for spokespeople.
Pictures, Numbers and Infographics
The key numbers in this lesson, each with its source:
| Number | What it is | Source |
|---|---|---|
| Jan. 17, 2025 | Date DORA began to apply to EU financial entities | Regulation (EU) 2022/25546 |
| 4 hours / 24 hours / 72 hours / 1 month | DORA major incident clocks: initial notice within 4 hours of classification and no later than 24 hours of awareness; intermediate report within 72 hours of the initial notice; final report within one month | Delegated Regulation (EU) 2025/30127 |
| At least every 3 years | DORA threat-led penetration testing for significant firms | DORA Article 26(1)6 |
| Up to 1 percent | Daily periodic penalty, as a share of average daily worldwide turnover, that the EU Lead Overseer can impose on a noncompliant critical provider | DORA Article 35(8)6 |
| 19 | Critical ICT third-party providers designated by the ESAs on Nov. 18, 2025 (count from a law firm summary) | ESAs; Morgan Lewis287 |
| $250 billion | Asset size of U.S. banking organizations the 2020 Sound Practices paper targets (or $100 billion with other risk indicators) | OCC Bulletin 2020-944 |
| 36 hours; 4 hours | Bank notice to its federal regulator of a notification incident; outage length that triggers a bank service provider's notice to its bank customers | 12 CFR Part 5322 |
| 2 hours | Resumption target for critical SCI systems after a wide-scale disruption; trading by the next business day | 17 CFR 242.100125 |
| At least annually | NYDFS testing of IR and BCDR plans and of restores from backup | 23 NYCRR 500.16(d)5 |
| Twice per year; every 2 years | Hospital emergency plan exercises; review of hospital emergency policies and communication plan | 42 CFR 482.1511 |
| 12 hours; 30 days | Federal agencies: perform essential functions within 12 hours of activation; sustain for at least 30 days | FEMA continuity directives, Aug. 20242012 |
| March 31, 2025 | Deadline for UK firms to remain within impact tolerances | FCA3 |
| About 192.7 million | People affected by the Change Healthcare attack, as of July 31, 2025 | HHS OCR29 |
| More than $6.5 billion | Advances and loans UnitedHealth made to providers by April 26, 2024 | Witty testimony8 |
| More than 15,000 | Dealers served by CDK Global in North America | Cybersecurity Dive9 |
| 8.5 million | Windows devices affected by the CrowdStrike update, July 2024 | Microsoft10 |
| About 99 percent | Share of Windows sensors back online by July 29, 2024 | CrowdStrike RCA31 |
| More than 100 | Free CISA Tabletop Exercise Packages | CISA13 |
| $900,000; $450,000; $330,440 | Idaho's estimated statewide grant-funded services for local governments: risk assessment, governance and planning, training | IOEM39 |
The chart below shows the clocks that can start in the first days of a disruptive cyber incident for a large regulated organization. Which apply depends on the organization's sector and locations.
Common mistakes
- Planning around the organization's own systems and forgetting the vendor that sits between it and its customers. Thousands of providers relied on one clearinghouse; when Change Healthcare went down, pharmacists submitted claims by hand and small practices struggled to make payroll, and UnitedHealth had to advance more than $6.5 billion to keep providers afloat.8 Fix: list the vendors behind each important service and test what happens if each is gone for 30 days.
- Treating a single remote door without multifactor sign-in as an IT detail. The Change Healthcare attackers entered through a portal that "did not have multi-factor authentication."8 The resilience program and the security program must share one list of critical assets.
- Assuming the recovery site is independent. The CrowdStrike update reached every Windows machine running the agent, wherever it sat, and Microsoft had to publish manual remediation steps.1031 Fix: for each high-privilege tool, know whether you control when updates reach critical machines, and plan for the tool itself failing.
- Not knowing whether operations can run without business IT. Colonial Pipeline stopped the pipeline as a precaution and judged that restoring IT would be quicker than running the whole system manually.32 Fix: map OT and field operations' dependence on business systems before the incident, and decide who may stop operations.
- Single-number time estimates in public. CDK's expectation of restoration "within several days, not weeks" appeared in a customer's SEC filing.9 Fix: communicate in stages and ranges.
- Plans that live only on the network that just went down. New York requires plans to be accessible "including during a cybersecurity event."5 Fix: printed and off-network copies, and an out-of-band contact method.
- Backups that the attacker can reach. The U.S. banking agencies' paper calls for protecting critical data against ransomware "including through secure, offline storage," and NYDFS requires backups "adequately protected from unauthorized alterations or destruction."15 Fix: isolated or immutable copies and restore tests, as in 108 lesson 7.
- Exercises that never change anything. The CMS rule requires hospitals to analyze every drill and real event and revise the plan; findings that repeat year after year signal a program that exercises for compliance only.11
- A continuity plan written for fire and flood. FEMA's 2024 directive lists a cyber incident as an activation trigger for federal continuity plans.12 Fix: make ransomware, data destruction and vendor loss standard scenarios.
Questions people ask
Is operational resilience just a new name for business continuity?
Partly, and the overlap is real. The difference is in the starting point and the owner: business continuity plans processes against threats, while operational resilience starts from the services the organization delivers, sets a board-approved limit on harm and tests against it.13 An organization with a strong continuity program is most of the way there; what it usually lacks is the explicit tolerance and the board's ownership of it.
Do we need ISO 22301 certification?
Usually not, unless customers or contracts ask for it. Service providers to banks and governments sometimes pursue it to answer due diligence questionnaires; most other organizations use it as a model. A certificate shows a management system exists and is audited; it does not show that a particular service will come back inside a particular time.16 Lesson 6 compares certifications.
Who should own business continuity?
The program is usually run by a business continuity office within operational or enterprise risk, the second line in the three lines model of lesson 8. Each business line owns its plans; IT owns disaster recovery; the CISO owns cyber incident response; and the board owns the tolerances. Placing the whole program inside IT tends to produce good disaster recovery and weak business continuity.
How often should we test?
Regulatory floors vary: at least annually under NYDFS for plans and restores, twice a year for hospital emergency plans, at least yearly under DORA for ICT continuity plans, and on FEMA's schedule for federal agencies.511612 A practical cycle is a tabletop for each important service yearly, an executive crisis exercise yearly, restore tests of critical systems at least yearly (quarterly for the most critical), and failover tests every one to two years for systems where failover is the strategy.
What does the board need to see?
The list of important services and their tolerances for approval; once a year, the results of tests against those tolerances, the gaps and the money to close them; the critical vendor concentrations the organization has accepted; and, within a day, any real event that breached or threatened a tolerance. The U.S. paper puts approval of the tolerance for disruption with the board, and DORA puts ultimate responsibility for ICT risk on the management body.16
Does DORA apply to a U.S. company?
Directly, only to EU-licensed financial entities, which include the EU subsidiaries of U.S. banks, insurers and asset managers. Indirectly, it reaches U.S. technology providers through their contracts with EU financial firms, and directly again if a U.S. provider is designated as critical, in which case it must designate an EU legal entity to work with its Lead Overseer.67
Should we keep a second provider for every critical service?
Not for every one; it can be costly and adds its own risks. For each critical service, compare the cost of a second provider (or an in-house fallback, or a manual process) with the harm of breaching tolerance, and let the board decide. Health care's experience in 2024 suggests the answer is yes for single industry-wide chokepoints such as clearinghouses and payment processors.8
Hard questions
Should U.S. regulators directly oversee cloud and critical technology providers, as the EU now does?
For: A handful of providers carry a large share of the economy's critical services. Customers individually have little power to inspect them, and the CrowdStrike and Change Healthcare events showed that one provider's error or breach can stop whole sectors. The EU has decided the risk justifies direct oversight with penalties.610 Against: The largest providers already face intense customer audits, certifications and market pressure; a second layer of supervision adds cost and may slow security updates; and U.S. bank regulators already have examination authority over bank service providers under the Bank Service Company Act.23 What the evidence shows: The U.S. relies on sector authority (banking examinations of service providers, contract terms and voluntary guidance) rather than a single oversight regime. Whether the EU model reduces outages will not be measurable for several years.
Are manual fallbacks worth what they cost?
For: Colonial ran parts of its pipeline by hand, pharmacists submitted claims manually, and dealers used workarounds; in each case the manual path kept some service going.3289 Against: Keeping paper processes current and staff trained costs real money, the skills fade as experienced staff retire (a point Blount himself raised), and manual processes have higher error and fraud rates.32 What the evidence shows: Manual fallbacks are most valuable where human safety or legal rights are at stake (hospitals, 911, elections, utilities) and least valuable where a fast clean rebuild is realistic. Many organizations will need both.
Should organizations disclose their impact tolerances and test results?
For: Customers, patients and investors bear the harm of outages and cannot judge resilience without information; public companies already describe cyber risk management in 10-K Item 1C.35 Against: Detailed recovery times and test gaps are a guide for attackers and extortionists; Idaho's public records law, for example, exempts emergency response plans and vulnerability assessments from disclosure for that reason.42 What the evidence shows: Regulators receive the detail confidentially (in the UK, self-assessments; under DORA, incident reports and registers); the public gets general descriptions. A middle path is to publish the existence of tolerances and testing, and the outcomes of real incidents, without technical specifics.
When systems are encrypted, is paying faster than rebuilding?
For paying: Some organizations, including Colonial, paid because they judged it could speed restoration of critical services.32 Against: Payment funds criminals, may violate sanctions, does not guarantee working decryption or deletion of stolen data, and the federal government advises against it; Change Healthcare's recovery still required rebuilding much of its environment.818 What the evidence shows: The organizations best placed to refuse are those with isolated, tested backups and a rebuild plan sequenced by the BIA, which turns the decision from an emergency into a choice. 108 lesson 10 covers the ransom decision in full.
For reporters and advocates
What public records exist.
- SEC filings. Form 8-K Item 1.05 and Item 8.01 filings and 10-K Item 1C describe incidents and resilience programs; when a vendor fails, its customers' filings often say more than the vendor does, as the CDK filings did.359
- Congressional hearings. Sworn testimony on Colonial Pipeline and Change Healthcare is public on govinfo.gov and the committees' websites, and gives executives' own accounts of decisions made in the first days.3243
- Vendor post-incident reports. CrowdStrike's root cause analysis is a model of what to ask any vendor for after an outage.31
- Health care. The HHS OCR breach portal and its Change Healthcare FAQ; state attorney general breach lists.2944
- EU and UK. The ESAs' list of designated critical providers and FCA publications on operational resilience.283
- Idaho public records. Under the Idaho Public Records Act (Idaho Code Title 74), ask a state agency whether its COOP plan is current and on file with IOEM as Executive Order 2022-04 requires, the date of its last continuity exercise and the after-action report's list of corrective actions, and ask counties whether they participate in IOEM's State and Local Cybersecurity Grant Program services.1439 Expect the plan's technical contents to be withheld: Idaho Code 74-105 exempts records such as emergency response plans and vulnerability assessments for critical infrastructure.42 Dates, existence, budgets and after-action summaries are often releasable.
Questions to ask after an outage. What are your important services, and what disruption had your board said it would tolerate? Did you stay within it? When did you first detect the problem, and when did you declare a crisis? Which regulators did you notify, and when? Which vendor was involved, and did you have an alternative? Did you have tested manual procedures, and did staff use them? Were your backups affected? When was the plan last exercised, and what did that exercise find? Did you pay a ransom?
Questions for public officials. How many state agencies have a current COOP plan on file, and when was each last exercised with a cyber scenario? Which county services (911 dispatch, elections, jail, payroll) have tested manual fallbacks? Which single vendors do multiple agencies depend on? What did the last statewide exercise find, and what has been fixed?
Words to watch. "Out of an abundance of caution" may be accurate (Colonial's shutdown was precautionary), but ask what the precaution protected against.32 "Restored" may mean a system is up while the backlog is weeks long; ask when service to people returned to normal. "No evidence of data theft" means nothing was found yet, not that nothing was taken.
Where to go next
- CISA Tabletop Exercise Packages: More than 100 ready-made exercise packages with scenarios, facilitator guidance and after-action templates. For continuity managers, CISOs, hospitals and local governments. No fee stated. Pick a ransomware or vendor-outage package and run it with the executive team.
- NIST SP 800-34 Rev. 1, Contingency Planning Guide: Free federal guide with BIA templates and plan outlines. For IT and continuity planners. Use its BIA template as a starting point and its definitions of MTD, RTO and RPO.
- Interagency Paper on Sound Practices to Strengthen Operational Resilience: Free. Written for the largest banks but readable by any board or risk officer. Use the seven areas as a checklist for your program.
- FEMA continuity resources and Federal Continuity Directives: Free. For federal, state and local continuity planners. Its testing schedule and four planning factors adapt well to any public agency.
- Idaho Office of Emergency Management: Continuity of Operations: Free. For Idaho state agencies, which must keep a current COOP plan on file with IOEM, and for local governments seeking guidance and exercise support.
- Basel Committee, Principles for Operational Resilience: Free international principles for banks. Useful for boards that want a short framework for resilience oversight.
- UK FCA operational resilience page: Free. The clearest public explanation of important business services and impact tolerances, with lessons from firms' first years.
Still being checked (6 items)
These points could not be fully confirmed against a primary source when this lesson was written and fact checked in November 2026. The text above states each one as uncertain.
- The count of 19 critical ICT third-party providers designated by the ESAs on Nov. 18, 2025 comes from a law firm summary; the ESAs' own list was not opened.
- The DORA incident reporting time limits were read from a secondary copy of Delegated Regulation (EU) 2025/301, not from EUR-Lex directly.
- The most recent edition, dates and participants of CISA's Cyber Storm national exercise could not be confirmed (CISA's page could not be loaded).
- Kootenai Health's figure of 464,088 people comes from SecurityWeek's report of a Maine attorney general filing, not the filing itself.
- The Regulation SCI annual testing reference (17 CFR 242.1004) is described in general terms and was not reread for this lesson.
- Whether NIST plans a revision of SP 800-34 was not confirmed; the CSRC page showed no draft revision as of Nov. 15, 2026.
Last verified November 15, 2026. General education, not legal, compliance, audit or other professional advice; rule versions and dates are stated in the text, and the sources used are listed in the Notes and Sources below. Check the regulator's current text before relying on any point.
Notes
- Board of Governors of the Federal Reserve System, SR 20-24, Interagency Paper on Sound Practices to Strengthen Operational Resilience (Nov. 2, 2020; letter and attachment revised June 2, 2026, the paper having been "revised to remove references to reputational risk"), attachment sections on governance, operational risk management, business continuity management, third-party risk management, scenario analysis, secure and resilient information systems management, and surveillance and reporting; Appendix A (cyber risk); Appendix B glossary definitions of operational resilience, critical operations, core business lines and tolerance for disruption (read Nov. 15, 2026). Read it online. ↩
- Marianne Swanson and others, Contingency Planning Guide for Federal Information Systems, NIST SP 800-34 Rev. 1 (May 2010, updated Nov. 11, 2010): the seven-step contingency planning process, the business impact analysis, the family of related plans (business continuity, continuity of operations, crisis communications, critical infrastructure protection, cyber incident response, disaster recovery, information system contingency and occupant emergency plans), and definitions of maximum tolerable downtime, recovery time objective and recovery point objective. No revision had been published as of the read date (read Nov. 15, 2026). Read it online. ↩
- Financial Conduct Authority (UK), "Operational resilience" page for firms: rules and guidance in force March 31, 2022; firms had until March 31, 2025 to be able to remain within impact tolerances for each important business service; impact tolerances describe "the maximum tolerable disruption" to a service "without causing harm to consumers, firms or markets"; mapping, scenario testing, communications and self-assessment (read Nov. 15, 2026). Read it online. ↩
- Office of the Comptroller of the Currency, Bulletin 2020-94, "Operational Risk: Sound Practices to Strengthen Operational Resilience" (Oct. 30, 2020), issued jointly with the Federal Reserve Board and the FDIC: the paper "does not set forth any new regulations or guidance"; aimed at domestic banking organizations with average total consolidated assets of $250 billion or more, or $100 billion or more with $75 billion or more in cross-jurisdictional activity, short-term wholesale funding, nonbank assets or off-balance-sheet exposure; "any bank may find elements of the sound practices useful" (read Nov. 15, 2026). Read it online. ↩
- 23 NYCRR 500.16, Incident response and business continuity management, as amended effective Nov. 1, 2023 (business continuity provisions effective Nov. 1, 2024): (a) written plans "to ensure operational resilience"; (a)(2) BCDR plan contents; (b) plans accessible "including during a cybersecurity event"; (c) training; (d) testing "at a minimum annually"; (e) protected backups. Cornell Legal Information Institute text (read Nov. 15, 2026). Read it online. ↩
- Regulation (EU) 2022/2554 of the European Parliament and of the Council of 14 December 2022 on digital operational resilience for the financial sector (DORA), OJ L 333, 27.12.2022, applying from Jan. 17, 2025 (Article 64): Article 2 (scope), Article 3 (definition of critical or important function), Article 5(2) (management body's "ultimate responsibility"), Articles 11 and 12 (ICT business continuity, testing "at least yearly," backup policies), Article 19 (major incident reporting), Article 26(1) (threat-led penetration testing "at least every 3 years"), Article 28(8) (exit strategies), Article 31 (designation of critical ICT third-party service providers) and Article 35(8) (periodic penalty payments "up to 1 %" of average daily worldwide turnover), EUR-Lex (read Nov. 15, 2026). Read it online. ↩
- Morgan Lewis, Sourcing at Morgan Lewis blog, "DORA: EU Regulators Announce List of Critical ICT Third-Party Providers" (November 2025): 19 providers designated on Nov. 18, 2025, in categories including hyperscale cloud, data center, infrastructure and network, and financial-services technology; designation criteria; EU coordination point; annual oversight fees; list updated yearly. Secondary source; the ESAs' list itself is the primary record (read Nov. 15, 2026). Read it online. ↩
- Andrew Witty, Chief Executive Officer, UnitedHealth Group, written testimony before the U.S. Senate Committee on Finance, May 1, 2024: Citrix portal that "did not have multi-factor authentication"; access Feb. 12 and ransomware Feb. 21, 2024; pharmacists "having to manually submit claims"; rebuilding Change Healthcare's environment; restoration priorities; more than $6.5 billion advanced as of April 26, 2024; "I am deeply sorry" (read Nov. 15, 2026). Read it online. ↩
- Cybersecurity Dive, coverage of the CDK Global cyberattack (June 24, 2024): discovered June 19, 2024; more than 15,000 dealers in North America; dealers "using workarounds to minimize disruption"; SEC filings by Sonic Automotive, Penske Automotive Group, AutoNation, Group 1 Automotive (relaying CDK's expectation of restoration "within several days, not weeks") and Lithia Motors (read Nov. 15, 2026). Read it online. ↩
- David Weston, Microsoft, "Helping our customers through the CrowdStrike outage" (July 20, 2024): update affected "8.5 million Windows devices, or less than one percent of all Windows machines"; hundreds of Microsoft engineers deployed; manual remediation documentation posted (read Nov. 15, 2026). Read it online. ↩
- 42 CFR 482.15, Condition of participation: Emergency preparedness (hospitals), eCFR current text: emergency plan based on a risk assessment; policies, procedures and communication plan "reviewed and updated at least every 2 years"; exercises "at least twice per year"; documentation and analysis of "all drills, tabletop exercises, and emergency events" (81 FR 64028, Sept. 16, 2016, as amended 84 FR 51817, Sept. 30, 2019) (read Nov. 15, 2026). Read it online. ↩
- Federal Emergency Management Agency, Office of National Continuity Programs, Federal Continuity Directive: Federal Executive Branch Continuity Program Management Requirements (August 2024), which rescinds and supersedes Federal Continuity Directive 1 (January 2017): four phases, four planning factors, sustainment "for a minimum of 30 days," testing, training and exercise schedule, cyber incident as an activation trigger, devolution and reconstitution (read Nov. 15, 2026). Read it online. ↩
- Cybersecurity and Infrastructure Security Agency, "CISA Tabletop Exercise Packages": "over 100 CTEPs available"; package contents; cyber, physical and cyber-physical scenarios. The page states no fee (read Nov. 15, 2026). Read it online. ↩
- Idaho Office of Emergency Management, "Continuity of Operations" page: Executive Order 2022-04 designates IOEM as coordinator of state and federal emergency response, recovery and mitigation operations and "requires each State Agency to maintain a current COOP Plan to be kept on file at the IOEM" (read Nov. 15, 2026). Read it online. ↩
- Office of the Comptroller of the Currency, Bulletin 2019-57, "FFIEC Information Technology Examination Handbook: Revised Business Continuity Management Booklet" (Nov. 14, 2019), replacing the Business Continuity Planning booklet of February 2015; quotations on resilience and the risk management life cycle (read Nov. 15, 2026). Read it online. ↩
- International Organization for Standardization, ISO 22301:2019, Security and resilience: Business continuity management systems: Requirements (paid standard; described from public summaries, not reproduced). Amended by ISO 22301:2019/Amd 1:2024 (climate action changes), as listed in national standards body catalogs such as SIS and BSI (read Nov. 16, 2026). Read it online. ↩
- Ron Ross and others, Developing Cyber-Resilient Systems: A Systems Security Engineering Approach, NIST SP 800-160 Vol. 2 Rev. 1 (December 2021), abstract: systems able to "anticipate, withstand, recover from, and adapt to adverse conditions, stresses, attacks, or compromises" (read Nov. 15, 2026). Read it online. ↩
- CISA, MS-ISAC, NSA and FBI, #StopRansomware Guide (updated 2023), prevention best practices including offline, encrypted and tested backups, and response checklist (read Nov. 15, 2026). Read it online. ↩
- National Institute of Standards and Technology, The NIST Cybersecurity Framework (CSF) 2.0, NIST CSWP 29 (Feb. 26, 2024): Recover function categories Incident Recovery Plan Execution (RC.RP) and Incident Recovery Communication (RC.CO); PR.DS-11 (backups) and PR.IR-03 (resilience requirements) (read Nov. 15, 2026). Read it online. ↩
- Federal Emergency Management Agency, Office of National Continuity Programs, Federal Continuity Directive: Federal Executive Branch Essential Functions Risk Identification and Management (August 2024), which rescinds and replaces Federal Continuity Directive 2 (June 2017): essential functions, business process analysis, business impact analysis, continuity options, review "every two years," performance "not later than 12 hours after continuity plan activation" and sustainment for at least 30 days (read Nov. 15, 2026). Read it online. ↩
- Basel Committee on Banking Supervision, Principles for Operational Resilience (March 31, 2021), seven principles on governance, operational risk management, business continuity planning and testing, mapping of interconnections and interdependencies, third-party dependency management, incident management, and resilient information and communication technology including cyber security (read Nov. 15, 2026). Read it online. ↩
- 12 CFR Part 53, Computer-Security Incident Notification (OCC), sections 53.3 (notice to the OCC as soon as possible and no later than 36 hours after determining a notification incident has occurred) and 53.4 (bank service provider notice for disruptions of "four or more hours"), adopted jointly with the Federal Reserve and FDIC, eCFR current text (read Nov. 15, 2026). Read it online. ↩
- Bank Service Company Act, 12 U.S.C. 1867(c)(1): services performed for a depository institution are subject to regulation and examination "to the same extent as if such services were being performed by the depository institution itself on its own premises," Cornell Legal Information Institute (read Nov. 15, 2026). Read it online. ↩
- Board of Governors of the Federal Reserve System, FDIC and OCC, "Interagency Guidance on Third-Party Relationships: Risk Management," 88 FR 37920 (June 9, 2023), final as of June 6, 2023, including termination and contingency planning in the third-party relationship life cycle (read Nov. 15, 2026). Read it online. ↩
- 17 CFR 242.1001(a)(2)(v), Regulation SCI: business continuity and disaster recovery plans "reasonably designed to achieve next business day resumption of trading and two-hour resumption of critical SCI systems following a wide-scale disruption," eCFR current text; see also 242.1004 on testing with designated members (read Nov. 15, 2026). Read it online. ↩
- 45 CFR 164.308(a)(7), HIPAA Security Rule contingency plan standard: data backup, disaster recovery and emergency mode operation plans (required); testing and revision procedures and applications and data criticality analysis (addressable), Cornell Legal Information Institute copy of the current text (read Nov. 15, 2026). Read it online. ↩
- Commission Delegated Regulation (EU) 2025/301 (OJ L, Feb. 20, 2025), supplementing DORA on the content and time limits of major incident reports, Article 5: initial notification "within four hours from the classification" and no later than 24 hours from awareness; intermediate report within 72 hours of the initial notification; final report no later than one month after the latest intermediate report. Text read from a secondary copy published by Advisera (read Nov. 15, 2026). Read it online. ↩
- European Supervisory Authorities (EBA, EIOPA and ESMA), press release, "European Supervisory Authorities designate critical ICT third-party providers under the Digital Operational Resilience Act" (Nov. 18, 2025), EIOPA copy (read Nov. 15, 2026). Read it online. ↩
- U.S. Department of Health and Human Services, Office for Civil Rights, Change Healthcare Cybersecurity Incident Frequently Asked Questions (update of July 31, 2025: "approximately 192.7 million individuals") (read Nov. 15, 2026). Read it online. ↩
- HHS Office for Civil Rights, Annual Report to Congress on Breaches of Unsecured Protected Health Information, calendar year 2024 (business associates: 106 of 663 large breach reports, 16 percent, affecting about 206.9 million people, 85 percent), as verified for module 108 (read Nov. 15, 2026). Read it online. ↩
- CrowdStrike, External Technical Root Cause Analysis: Channel File 291 (Aug. 6, 2024): about 99 percent of Windows sensors online as of July 29, 2024; staged deployment through rings; customer control over where and when Rapid Response Content is deployed; independent third-party reviews (read Nov. 15, 2026). Read it online. ↩
- U.S. Senate Committee on Homeland Security and Governmental Affairs, Threats to Critical Infrastructure: Examining the Colonial Pipeline Cyberattack, S. Hrg. 117-429 (June 8, 2021), testimony and answers of Joseph Blount, chief executive of Colonial Pipeline Company (precautionary shutdown, manual operation of small portions, field crews reading gauges, $4.4 million ransom, communication through one federal conduit, aging workforce) (read Nov. 15, 2026). Read it online. ↩
- Alex Nelson and others, Incident Response Recommendations and Considerations for Cybersecurity Risk Management: A CSF 2.0 Community Profile, NIST SP 800-61 Rev. 3 (April 3, 2025) (read Nov. 15, 2026). Read it online. ↩
- New York State Department of Financial Services, "Cybersecurity Submissions" page, on notices under 23 NYCRR 500.17 (cybersecurity incident notice within 72 hours of determination) (read Nov. 15, 2026). Read it online. ↩
- U.S. Securities and Exchange Commission, Cybersecurity Risk Management, Strategy, Governance, and Incident Disclosure, Release No. 33-11216, 88 FR 51896 (Aug. 4, 2023): Form 8-K Item 1.05 due within four business days after a materiality determination; Regulation S-K Item 106, reported in 10-K Item 1C (read Nov. 15, 2026). Read it online. ↩
- Tim Grance and others, Guide to Test, Training, and Exercise Programs for IT Plans and Capabilities, NIST SP 800-84 (September 2006) (read Nov. 15, 2026). Read it online. ↩
- Idaho Code 46-1006, Powers and duties of chief and office (State Disaster Preparedness Act), as published on the Idaho Legislature website through the 2026 session (read Nov. 15, 2026). Read it online. ↩
- Idaho Code 46-1009, Local and intergovernmental disaster agencies and services, as published on the Idaho Legislature website through the 2026 session (read Nov. 15, 2026). Read it online. ↩
- Idaho Office of Emergency Management, "State and Local Cybersecurity Grant Program" page: services in lieu of direct grants; estimated statewide costs of $900,000 (risk assessment and gap management), $450,000 (cybersecurity governance and planning) and $330,440 (training); Cybersecurity Area Field Officers; eligible local entities (page refers to the federal fiscal year 2022 grant) (read Nov. 15, 2026). Read it online. ↩
- SecurityWeek, "460k Impacted by Kootenai Health Ransomware Attack" (August 2024), citing the Maine attorney general filing (464,088 people). Secondary source (read Nov. 15, 2026). Read it online. ↩
- Idaho Code 28-51-105, Disclosure of breach of security of computerized personal information, including notice by public agencies to the Idaho Attorney General within 24 hours of discovering a breach, as published through the 2026 session (read Nov. 15, 2026). Read it online. ↩
- Idaho Code 74-105, Records exempt from disclosure, including subsection (4)(b) on critical infrastructure records such as vulnerability assessments and emergency response plans, as published through the 2026 session (read Nov. 15, 2026). Read it online. ↩
- U.S. Senate Committee on Finance, Hacking America's Health Care: Assessing the Change Healthcare Cyberattack and What's Next, S. Hrg. 118-785 (May 1, 2024) (read Nov. 15, 2026). Read it online. ↩
- Idaho Office of the Attorney General, Consumer Protection, "Security Breaches" notice list (read Nov. 15, 2026). Read it online. ↩
Check yourself
1. Which statement best describes operational resilience as the 2020 interagency Sound Practices paper uses the term?
The OCC, Federal Reserve and FDIC paper (OCC Bulletin 2020-94, Oct. 30, 2020) defines operational resilience as the ability to deliver operations, including critical operations and core business lines, through a disruption from any hazard.
2. Who should set and approve an impact tolerance (tolerance for disruption) for an important service?
The interagency paper places approval of the tolerance for disruption with the board, and the FCA's rules have firms set tolerances for important business services based on harm to consumers and markets, not on IT capability.
3. Under the EU's Commission Delegated Regulation (EU) 2025/301 supplementing DORA, when is the initial notification of a major ICT-related incident due?
Article 5 of Delegated Regulation 2025/301 sets the initial notification within four hours from classification and no later than 24 hours from awareness; the intermediate report follows within 72 hours of the initial notice.
4. What does 23 NYCRR 500.16(d) require of New York DFS-regulated entities?
23 NYCRR 500.16(d), as amended Nov. 1, 2023, requires testing at a minimum annually of the IR and BCDR plans and of the ability to restore from backups.
5. How often must hospitals under the Medicare conditions of participation exercise their emergency plan?
42 CFR 482.15(d)(2) requires hospitals to conduct exercises to test the emergency plan at least twice per year.
6. Which recovery target is written into the SEC's Regulation SCI for critical SCI systems after a wide-scale disruption?
17 CFR 242.1001(a)(2)(v) requires plans reasonably designed to achieve next business day resumption of trading and two-hour resumption of critical SCI systems.
7. What did CrowdStrike change after the July 2024 outage, according to its Aug. 6, 2024 root cause analysis?
The root cause analysis lists staged deployment with rollback and new customer controls over the delivery of Rapid Response Content.
8. Under FEMA's August 2024 Federal Continuity Directive on essential functions, how quickly must federal agencies be able to perform essential functions after continuity plan activation?
The directive requires performance as soon as possible, but not later than 12 hours after activation, and sustainment for at least 30 days; it replaced FCD 2 of June 2017.
9. What does Idaho Executive Order 2022-04 require of state agencies, according to the Idaho Office of Emergency Management?
IOEM's Continuity of Operations page says EO 2022-04 requires each state agency to maintain a current COOP plan to be kept on file at IOEM.
10. For ICT services that support critical or important functions, what does DORA Article 28(8) require EU financial entities to have?
Article 28(8) of Regulation (EU) 2022/2554 states that financial entities shall put in place exit strategies for such services, and the plans must be tested and reviewed periodically.
Terms in this lesson
- Operational resilience
- The ability to deliver operations, including critical operations and core business lines, through a disruption from any hazard (U.S. interagency Sound Practices paper, 2020).
- Business continuity management
- The ongoing program that keeps business processes running during and after a disruption, covering people, places, suppliers, technology and manual workarounds.
- Disaster recovery
- Restoring information systems, data and facilities after a disruption, usually at an alternate site or cloud region.
- Business impact analysis (BIA)
- An analysis of an organization's processes that measures how harm grows over time when each stops, maps dependencies, and sets recovery priorities and targets (NIST SP 800-34 Rev. 1).
- Impact tolerance
- The maximum tolerable level of disruption to an important service, usually stated as time, beyond which harm to customers, markets or the organization would be intolerable; called tolerance for disruption in U.S. banking guidance.
- Important business service
- Under UK rules, a service whose disruption could cause intolerable harm to consumers or markets; the unit for which impact tolerances are set.
- Critical or important function
- Under DORA, a function whose disruption would materially impair a financial entity's performance, soundness, continuity of services or compliance with its authorization.
- Severe but plausible scenario
- A disruption scenario serious enough to test whether an important service would stay within tolerance, and realistic because something like it has happened.
- Concentration risk
- The risk that many important services depend on one provider, technology, location or person, so a single failure stops them all.
- Exit strategy
- A tested plan for leaving or replacing a critical provider in a planned or sudden exit, covering alternatives, data return, contract terms and cost.
- Downtime procedures
- Manual processes, forms and pre-staged information that let a hospital or other organization keep operating safely while its systems are unavailable.
- Continuity of operations (COOP)
- A government agency's capability to keep performing its essential functions during a disruption, including delegation of authority, alternate sites, devolution and reconstitution.
- Devolution
- Transferring statutory authority and responsibility for essential functions to other staff or sites when the primary organization cannot perform them (FEMA, 2024).
- Critical ICT third-party service provider (CTPP)
- A technology provider designated by the EU's European Supervisory Authorities for direct oversight under DORA because of its systemic importance to the financial sector.
- After-action report
- The written review after an exercise or real event listing what worked, what did not, root causes, and corrective actions with owners and dates.
Sources
- Interagency Paper on Sound Practices to Strengthen Operational Resilience (SR 20-24 attachment, revised June 2026) (2020-11-02) checked 2026-11
- OCC Bulletin 2020-94, Sound Practices to Strengthen Operational Resilience (2020-10-30) checked 2026-11
- OCC Bulletin 2019-57, Revised FFIEC Business Continuity Management Booklet (2019-11-14) checked 2026-11
- NIST SP 800-34 Rev. 1, Contingency Planning Guide for Federal Information Systems (2010-11-11) checked 2026-11
- Regulation (EU) 2022/2554, Digital Operational Resilience Act (2022-12-27) checked 2026-11
- 23 NYCRR 500.16, Incident response and business continuity management (2023-11-01) checked 2026-11
- 42 CFR 482.15, Emergency preparedness (hospitals) (2019-09-30) checked 2026-11
- 17 CFR 242.1001, Regulation SCI obligations (2014-12-05) checked 2026-11
- FEMA, Federal Continuity Directive: Continuity Program Management Requirements (2024-08-01) checked 2026-11
- FEMA, Federal Continuity Directive: Essential Functions Risk Identification and Management (2024-08-01) checked 2026-11
- Andrew Witty testimony, Senate Finance Committee (2024-05-01) checked 2026-11
- CrowdStrike, External Technical Root Cause Analysis: Channel File 291 (2024-08-06) checked 2026-11
- Senate Homeland Security hearing on the Colonial Pipeline cyber attack, S. Hrg. 117-429 (2021-06-08) checked 2026-11
- Idaho Office of Emergency Management, Continuity of Operations (2026-11-15) checked 2026-11